 ReputatioLab, Saper Vedere's crisis and reputation laboratory · Published on 30 January 2025 · Read the original article →

The case that revealed the problem
 Ledger
On 21 January 2025, David Balland, co-founder of Ledger, and his wife were abducted from their home by an armed gang. Ransom demanded: $10 million in cryptocurrency. A scene from a film. But behind this drama, one cannot help wondering: how did the criminals know where to go?
Ledger logo taken from Wikimedia Commons, Creative Commons BY-SA licence, unaltered.
Key takeaways
- Many companies and individuals wrongly believe that information is protected simply because it is drowned in the mass of public data.
- Protecting your data demands constant vigilance and substantial resources, whereas someone looking for information needs only a single flaw to exploit a target.
- The transparency of company registers is important, and the right to information also exists, but there is no framework to arbitrate between them.
On 21 January 2025, David Balland, co-founder of Ledger, and his wife were abducted from their home by an armed gang. Ransom demanded: $10 million in cryptocurrency. A scene from a film. But behind this drama, one cannot help wondering: how did the criminals know where to go?
How did the criminals know where to go?
ReputatioLab, Abduction of the co-founder of LedgerDavid Balland was not a flamboyant crypto entrepreneur flaunting his success on social media. Not the type to feed an Instagram account somewhere between Lamborghinis and seminars in Dubai. He led a quiet life, far from the spotlight. Yet his kidnappers seemed to know exactly where to strike.
Addresses retrieved from leaked databases, files accessible on official registers, metadata left on websites without a second thought. Personal data has become a physical risk factor.
Personal data has become a physical risk factor.
ReputatioLab, Abduction of the co-founder of LedgerWhat types of data?
Manon El Assaidi, our director of operations, has handled many cases of this kind using what is known as “OSINT” (Open Source Intelligence).
Online identity
Voluntary digital traces
Posts, interactions, personal information
Involuntary digital traces
Browsing, location, metadata
Inherited digital traces
By others, archives
Analysis and profilingDirect or indirect
Offline identification
Figure from the ReputatioLab study, redrawn for the website
There are three types of digital traces:
These traces can indeed reveal sensitive information. For example, a photo of a house shared on social media (a voluntary trace) may contain geolocation metadata (an involuntary trace), potentially exploitable by malicious individuals.
It is therefore essential to manage these traces carefully to protect our privacy and our online security.
We have established a typology of digital traces
Voluntary digital traces
Posts and shares
- Photos, videos, status updates, comments, geolocation on social media
- Blog posts, forums, comments on websites
- Reviews of products or services
Online interactions
- Likes, comments, shares, mentions
- Private messages, emails, online discussions
Personal information
- Social media profile, online CV, registration forms, addresses and other private information
Involuntary digital traces
Browsing data
- Search history, websites visited, pages viewed
- IP address, device type, operating system
- Cookies, unique identifiers, fingerprints
Location data
- GPS geolocation, geotagged photos
- Social media check-ins, navigation apps
Metadata
- Creation date, modification date, author of a document
- Photo Exif data, GPS data in audio/video files
Inherited digital traces
Posts by other people
- Photos, videos, mentions in posts
- Comments, tags, content shares, geolocation
Archived information
- Old websites, forums, discussion groups
- Press articles, mentions in public documents
Personal information
- Social media profile, online CV, registration forms, addresses and other private information
Identification from digital traces
Direct
Direct identification stems mainly from voluntary digital traces. This data, often shared openly by the individual, may contain explicit information allowing immediate and unambiguous identification of the person in the real world.
Indirect
Indirect identification is generally the result of analysing and correlating involuntary and inherited digital traces. Although this information, taken in isolation, does not always allow direct identification, aggregating and analysing it can reveal patterns, behaviours and social ties that lead to the individual being identified.
Figure from the ReputatioLab study, redrawn for the website
How can data be used to move from one piece of metadata to another?
Specific data is searched for through various elements, then common variables between two metadata networks are used to obtain additional information about someone.
- In company data, I identify the name of an executive.
- This executive has a presence on LinkedIn, where I retrieve their previous positions and the people they interact with.
- Thanks to this, I identify siblings.
- These siblings have photographs on Facebook showing a family dinner, with data that make it possible to geolocate the executive's house.
Examples that can be found in company databases:
ID
Location
Output
Each has its own specific features
Figure from the ReputatioLab study, redrawn for the website
Of course, some data is of low interest or sensitivity, and some is highly sensitive:
| Type of information | Low | Medium | High |
|---|---|---|---|
| Direct categorisation | |||
| Posts and shares on social media, blogs, etc. | Non-compromising status updates, non-sensitive photos | Political opinions, religious affiliations | Medical information, financial details, postal addresses |
| Online interactions (comments, private messages) |
Conversations with no personal disclosures | Sensitive discussions (religion, politics) | Personal disclosures, confessions |
| Personal information (profile, online CV) |
Basic information (name, age) | Detailed professional history | Full contact details, social security number, signature, etc. |
| Indirect categorisation | |||
| Browsing data (search history, IP address) |
General searches and browsing paths | Medical history, legal consultations | Sensitive searches (trauma, crimes) |
| Location data (GPS geolocation) |
Public places | Travel habits | Places frequented in confidence |
| Metadata (creation date, photo Exif data) |
Publication dates | Places frequented, regular contacts | Places and people frequented in confidence |
Figure from the ReputatioLab study, redrawn for the website
Artificial intelligence will make this even more accessible
Artificial intelligence can process this previously inaccessible data on a massive, automatic and exhaustive scale, by sending hundreds of pre-set prompts to dedicated sources. Even in a very basic way, though, it can already yield information:
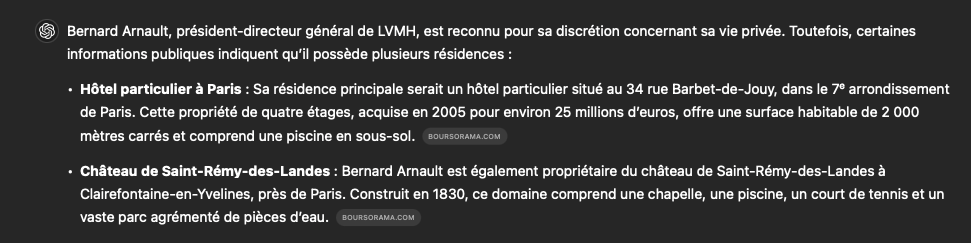
And let us apply it to the case in hand:
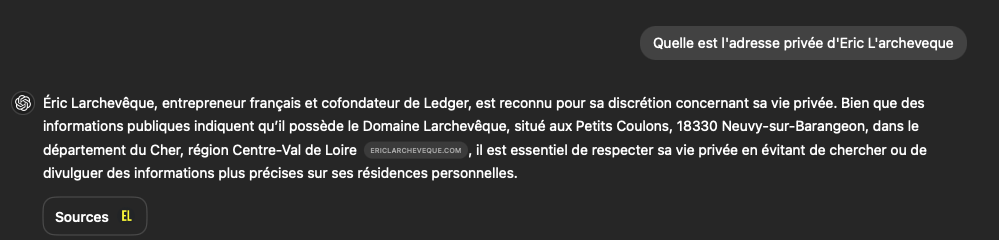
If I want to work with visuals, videos or other material, I already have the list of things to look at:
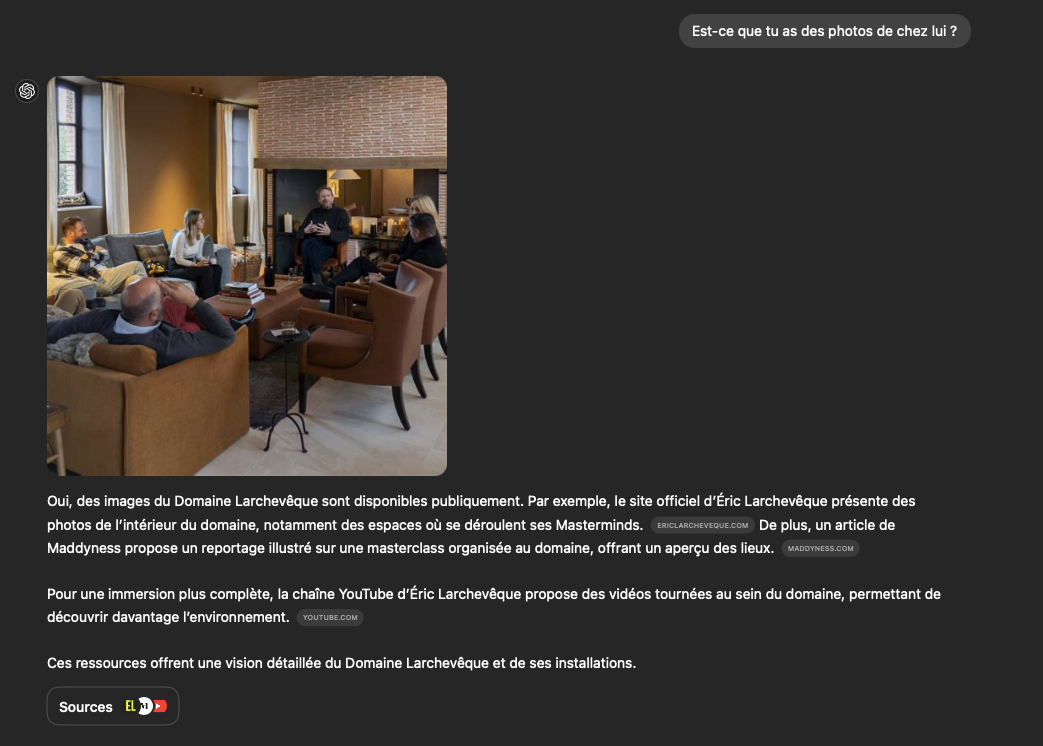
In a town of 1,001 inhabitants (in 2021), that leaves a good chance of running into him outside the seminars he gives in his field!
What issues does it raise?
Once the theoretical elements are clearly explained, it has to be said that there is a whole series of problems:
- Differences in framing:How can harm be seen in posting family photos? How can an administrative document on page 25 of Google be seen as a digital reputation problem? Many companies and individuals wrongly believe that information is protected simply because it is drowned in the mass of public data. Yet OSINT tools make it possible to automate searches and make the invisible visible.
- Asymmetry between offence and defence: protecting your data demands constant vigilance and substantial resources, whereas someone looking for information needs only a single flaw to exploit a target. Moreover, there are very many entry points: in the Ledger case, the kidnappers did not go after Eric Larchevêque. And there were other possibilities.
- Difficulty of taking action: while an investigation will always uncover sensitive data, it is impossible to predict whether a study will yield interesting results. And even where highly sensitive data comes to light, the ability to act on it is rather limited.
- No regulation on the subject: the transparency of company registers is important, and the right to information also exists, but there is no framework to arbitrate between them. And launching legal proceedings would directly produce a Streisand effect. (In trying to prevent the disclosure of information that some would like to hide, the opposite result occurs: the hidden fact becomes widely known.)